What mechanism lets Transformers weigh input tokens?
Select an option, then click Submit answer.
- ○ Self-attention mechanism in layers
- ○ Recurrent hidden state loop
- ○ Convolution filter weight sharing
- ○ Pooling window down sampling
Loading demo links...
Showing 1–12 of 12 questions
What mechanism lets Transformers weigh input tokens?
Select an option, then click Submit answer.
What does pre-training of large models use?
Select an option, then click Submit answer.
Which component encodes token position in Transformers?
Select an option, then click Submit answer.
What is the main role of the decoder in GPT models?
Select an option, then click Submit answer.
Which scaling factor stabilises attention scores?
Select an option, then click Submit answer.
What does a mixture-of-experts layer do?
Select an option, then click Submit answer.
Which two are Transformer components? (Choose two.)
Select all that apply, then click Submit answer.
Which two affect generation randomness? (Choose two.)
Select all that apply, then click Submit answer.
Which two describe large model training stages? (Choose two.)
Select all that apply, then click Submit answer.
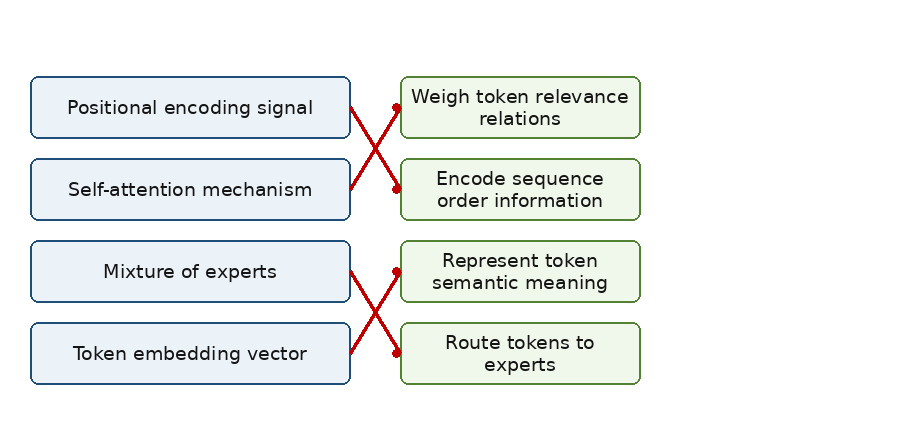
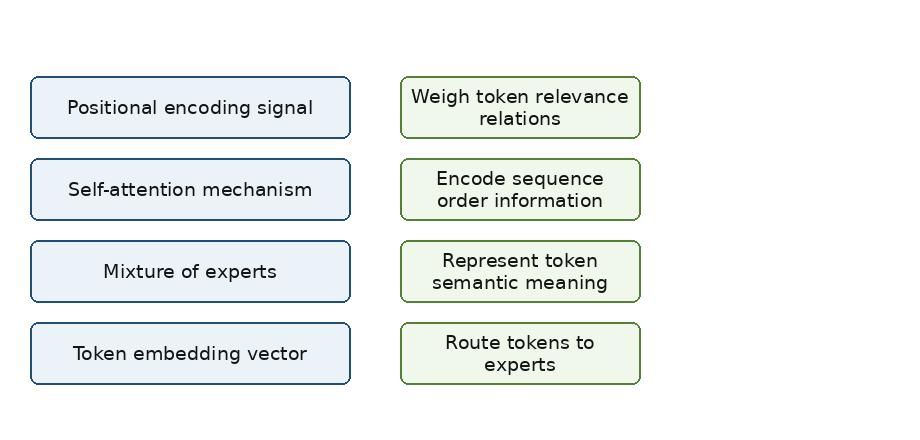
DRAG DROP
Match each model concept to its meaning.
Items to match: Self-attention mechanism, Positional encoding signal, Token embedding vector, Mixture of experts.

Answer is in the explanation below.
CORRECT TEXT
The Transformer component that weighs token relevance is called self-______.
Answer is in the explanation below.
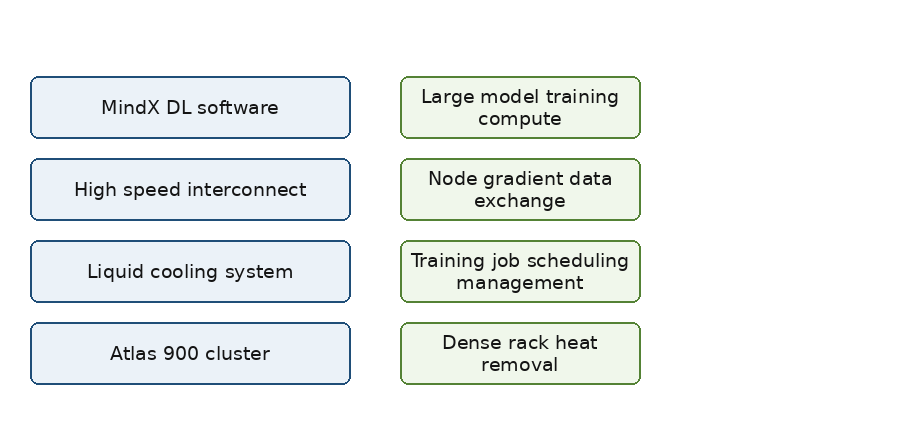
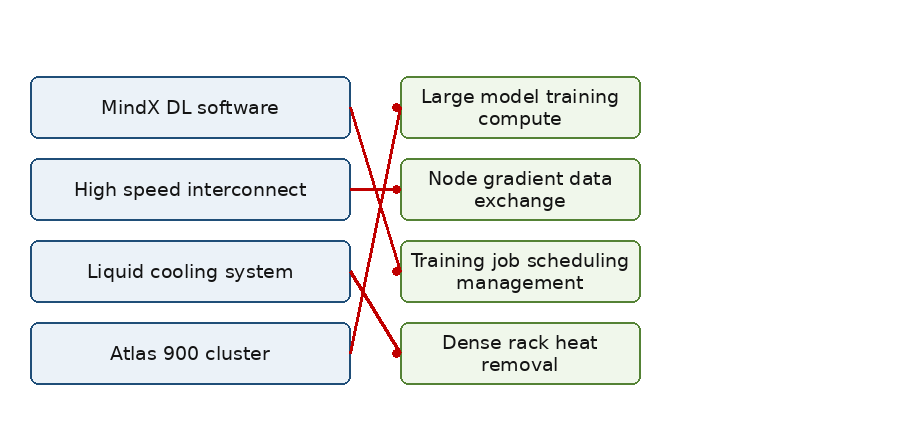
DRAG DROP
Match each center element to its role.
Items to match: Atlas 900 cluster, High speed interconnect, MindX DL software, Liquid cooling system.

Answer is in the explanation below.