When is Spark ML preferred over single-node libraries?
Select an option, then click Submit answer.
- ○ Dataset exceeds single machine memory
- ○ Dataset fits easily in memory
- ○ Only text features are used
- ○ Model must run offline only
Loading demo links...
Showing 1–12 of 12 questions
When is Spark ML preferred over single-node libraries?
Select an option, then click Submit answer.
What does a Spark ML Pipeline combine into one workflow?
Select an option, then click Submit answer.
What is the role of StringIndexer in a pipeline?
Select an option, then click Submit answer.
Why is VectorAssembler used before most Spark ML estimators?
Select an option, then click Submit answer.
Which component learns parameters from training data?
Select an option, then click Submit answer.
What does CrossValidator do in Spark ML tuning?
Select an option, then click Submit answer.
Which two are Spark ML pipeline stages? (Choose two.)
Select all that apply, then click Submit answer.
Which two help tune a Spark ML model? (Choose two.)
Select all that apply, then click Submit answer.
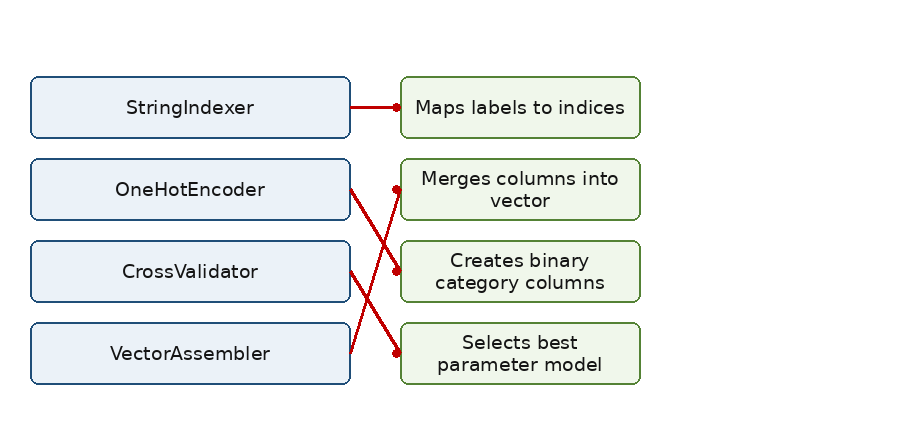
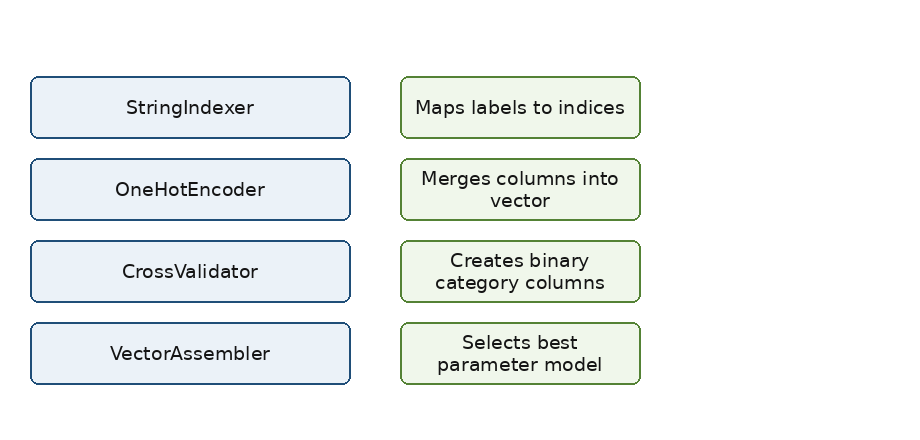
DRAG DROP
Match each component to its function.
Items to match: StringIndexer, VectorAssembler, OneHotEncoder, CrossValidator.

Answer is in the explanation below.
CORRECT TEXT
In Spark ML, an algorithm that learns from data by fitting is called an ______.
Answer is in the explanation below.
Which two support distributed hyperparameter tuning? (Choose two.)
Select all that apply, then click Submit answer.
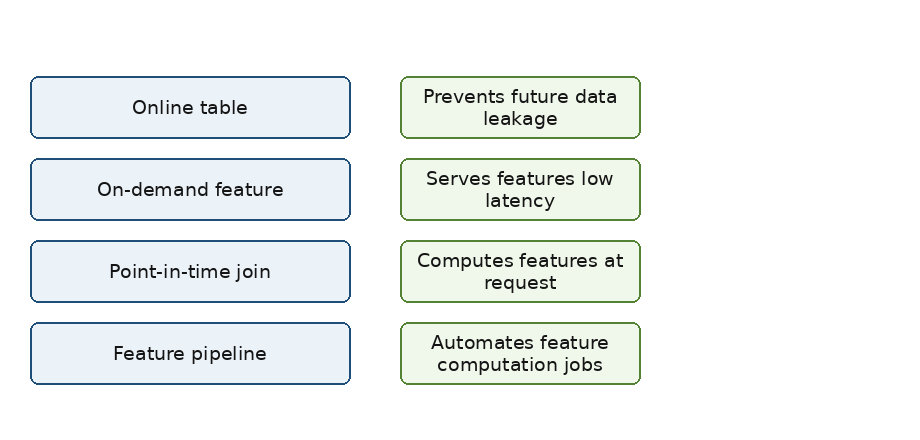
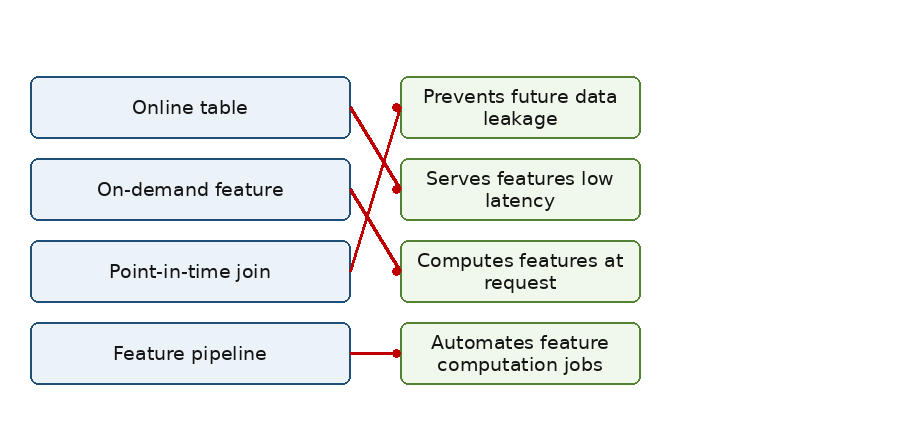
DRAG DROP
Match each Feature Store concept to its purpose.
Items to match: Point-in-time join, Online table, On-demand feature, Feature pipeline.

Answer is in the explanation below.