Which of the following DataFrame operations is classified as an action?
Select an option, then click Submit answer.
- ○ DataFrame.drop()
- ○ DataFrame.coalesce()
- ○ DataFrame.take()
- ○ DataFrame.join()
- ○ DataFrame.filter()
Loading demo links...
Showing 1–23 of 23 questions
Which of the following DataFrame operations is classified as an action?
Select an option, then click Submit answer.
Which of the following operations can be used to create a DataFrame with a subset of columns from DataFrame storesDF that are specified by name?
Select an option, then click Submit answer.
The code block shown below contains an error. The code block is intended to return a new DataFrame with the mean of column sqft from DataFrame storesDF in column sqftMean. Identify the error. Code block: storesDF.agg(mean("sqft").alias("sqftMean"))
Select an option, then click Submit answer.
The code block shown below contains an error. The code block is intended to create a Python UDF assessPerformanceUDF() using the integer-returning Python function assessPerformance() and apply it to column customerSatisfaction in DataFrame storesDF. Identify the error. Code block: assessPerformanceUDF – udf(assessPerformance) storesDF.withColumn("result", assessPerformanceUDF(col("customerSatisfaction")))
Select an option, then click Submit answer.
The code block shown below contains an error. The code block is intended to use SQL to return a new DataFrame containing column storeId and column managerName from a table created from DataFrame storesDF. Identify the error. Code block: storesDF.createOrReplaceTempView("stores") storesDF.sql("SELECT storeId, managerName FROM stores")
Select an option, then click Submit answer.
The code block shown below contains an error. The code block is intended to return a DataFrame containing a column openDateString, a string representation of Java’s SimpleDateFormat. Identify the error. Note that column openDate is of type integer and represents a date in the UNIX epoch format – the number of seconds since midnight on January 1st, 1970. An example of Java’s SimpleDateFormat is "Sunday, Dec 4, 2008 1:05 PM". A sample of storesDF is displayed below: Code block: storesDF.withColumn("openDateString", from_unixtime(col("openDate"), "EEE, MMM d, yyyy h:mm a", TimestampType()))

Select an option, then click Submit answer.
The code block shown below contains an error. The code block is intended to return a new DataFrame that is the result of a cross join between DataFrame storesDF and DataFrame employeesDF. Identify the error. Code block: storesDF.join(employeesDF, "cross")
Select an option, then click Submit answer.
In what order should the below lines of code be run in order to write DataFrame storesDF to file path filePath as parquet and partition by values in column division? Lines of code: 1. .write() \ 2. .partitionBy("division") \ 3. .parquet(filePath) 4. .storesDF \ 5. .repartition("division") 6. .write \ 7. .path(filePath, "parquet")
Select an option, then click Submit answer.
The code block shown below contains an error. The code block intended to read a parquet at the file path filePath into a DataFrame. Identify the error. Code block: spark.read.load(filePath, source – "parquet")
Select an option, then click Submit answer.
Which of the following operations can be used to return a DataFrame with no duplicate rows? Please select the most complete answer.
Select an option, then click Submit answer.
Which of the following code blocks will always return a new 4-partition DataFrame from the 8-partition DataFrame storesDF without inducing a shuffle?
Select an option, then click Submit answer.
The code block shown below contains an error. The code block is intended to adjust the number of partitions used in wide transformations like join() to 32. Identify the error. Code block: spark.conf.set("spark.default.parallelism", "32")
Select an option, then click Submit answer.
The code block shown below contains an error. The code block is intended to create and register a SQL UDF named “ASSESS_PERFORMANCE” using the Scala function assessPerformance() and apply it to column customerSatisfaction in the table stores. Identify the error. Code block: spark.udf.register(“ASSESS_PERFORMANCE”, assessPerforance) spark.sql(“SELECT customerSatisfaction, assessPerformance(customerSatisfaction) AS result FROM stores”)
Select an option, then click Submit answer.
Which of the following pairs of arguments cannot be used in DataFrame.join() to perform an inner join on two DataFrames, named and aliased with "a" and "b" respectively, to specify two key columns column1 and column2?
Select an option, then click Submit answer.
Which of the following best describes the similarities and differences between the MEMORY_ONLY storage level and the MEMORY_AND_DISK storage level?
Select an option, then click Submit answer.
The code block shown below should return a new DataFrame where column division from DataFrame storesDF has been renamed to column state and column managerName from DataFrame storesDF has been renamed to column managerFullName. Choose the response that correctly fills in the numbered blanks within the code block to complete this task. Code block: storesDF. __1__(__2__, __2__).__4__(__5__, __6__)
Select an option, then click Submit answer.
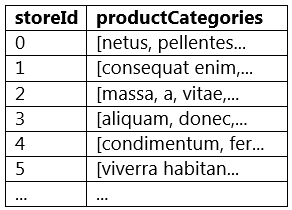
The code block shown below should return a new DataFrame where column productСategories only has one word per row, resulting in a DataFrame with many more rows than DataFrame storesDF. Choose the response that correctly fills in the numbered blanks within the code block to complete this task. A sample of storesDF is displayed below: Code block: storesDF.__1__(__2__, __3__(__4__(__5__)))

Select an option, then click Submit answer.
The code block shown below should print the schema of DataFrame storesDF. Choose the response that correctly fills in the numbered blanks within the code block to complete this task. Code block: __1__.__2__(__3__)
Select an option, then click Submit answer.
The code block shown below should read a parquet at the file path filePath into a DataFrame. Choose the response that correctly fills in the numbered blanks within the code block to complete this task. Code block: __1__.__2__.__3__(__4__)
Select an option, then click Submit answer.
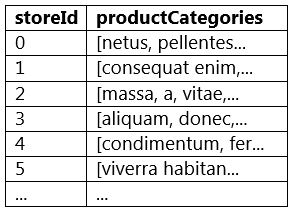
The code block shown below contains an error. The code block is intended to return a new DataFrame where column productCategories only has one word per row, resulting in a DataFrame with many more rows than DataFrame storesDF. Identify the error and how to fix it. A sample of storesDF is displayed below: storesDF.withColumn("productCategories", split(col("productCategories")))

Select an option, then click Submit answer.
If Spark is running in cluster mode, which of the following statements about nodes is incorrect?
Select an option, then click Submit answer.
A data scientist is working on a large dataset in Apache Spark using PySpark. The data scientist has a DataFrame df with columns ‘user_id’, 'product_id’, and ‘purchase_amount’ and needs to perform some operations on this data efficiently. Which sequence of operations results in transformations that require shuffle followed by transformations that do not?
Select an option, then click Submit answer.
A data scientist is working on a project that requires processing large amounts of structured data, performing SQL queries, and applying machine learning algorithms. The data scientist is considering using Apache Spark for this task. Which combination of Apache Spark modules should the data scientist use in this scenario?
Select an option, then click Submit answer.
Prepare for the Certified Associate Developer for Apache Spark (CERTIFIED-ASSOCIATE-DEVELOPER-FOR-APACHE-SPARK) exam with this free practice test from Study4Pass, built around the real Databricks syllabus. The 23 questions are a free sample of the full Study4Pass practice set of 342 questions, so you can check your level before you commit to the real exam. The free sample is made up of 23 single-answer questions, each with a full explanation. The Databricks CERTIFIED-ASSOCIATE-DEVELOPER-FOR-APACHE-SPARK exam is part of the Certified Associate Developer for Apache Spark certification.
The target audience of the Databricks CERTIFIED-ASSOCIATE-DEVELOPER-FOR-APACHE-SPARK exam is professionals who want to validate their skills in Certified Associate Developer for Apache Spark and demonstrate their competency to employers. The prerequisites of the Databricks CERTIFIED-ASSOCIATE-DEVELOPER-FOR-APACHE-SPARK exam, if any, are defined by Databricks in the official exam guide.
Treat this sample as a diagnostic. Answer honestly, check the explanation after every question, and note which topics feel shaky. A short, focused review of those topics is worth more than re-reading everything — and the full set lets you drill them topic by topic.
A good way to use this page: take the whole sample in one sitting, then go back over every explanation with fresh eyes. Mark the topics that felt uncertain, not just the ones you got wrong — uncertain answers are unmarked risk on the real exam. One or two focused passes like this usually move a score more than days of passive reading.
Inside the full CERTIFIED-ASSOCIATE-DEVELOPER-FOR-APACHE-SPARK practice set:
Answer a question, then check the result to see the correct answer and the explanation behind it. Work at your own pace — there is no timer and no signup. Stuck on a concept? This is an AI-Enabled practice test: use Ask AI on any question and get the underlying concept explained in plain words, so you learn the reasoning instead of memorizing answers. When the free sample feels comfortable, the full set of 342 questions adds timed Exam Simulation, topic-by-topic training, and flagged-question review — the closest thing to exam day you can get before the real thing.
The CERTIFIED-ASSOCIATE-DEVELOPER-FOR-APACHE-SPARK practice set is built to mirror the full Certified Associate Developer for Apache Spark syllabus, so every major area of the real exam is represented in the questions. The Databricks CERTIFIED-ASSOCIATE-DEVELOPER-FOR-APACHE-SPARK exam is part of the Certified Associate Developer for Apache Spark certification. The most reliable study method with a set like this is simple: practise a section, read the explanations, then go back to the official Databricks documentation for any topic you missed, and repeat until the explanations feel obvious.
Yes. Every question on this page — all 23 of them — is free to use, and you never need to create an account to try them.
The full Study4Pass set for CERTIFIED-ASSOCIATE-DEVELOPER-FOR-APACHE-SPARK has 342 practice questions. This page gives you 23 of them free so you can judge the quality and difficulty first.
Yes. Check any question to reveal the correct answer and its explanation, and use Ask AI whenever you want the underlying concept explained step by step.
No — these are practice questions built to match the CERTIFIED-ASSOCIATE-DEVELOPER-FOR-APACHE-SPARK domains and difficulty level, so you can prepare for the real exam with confidence.